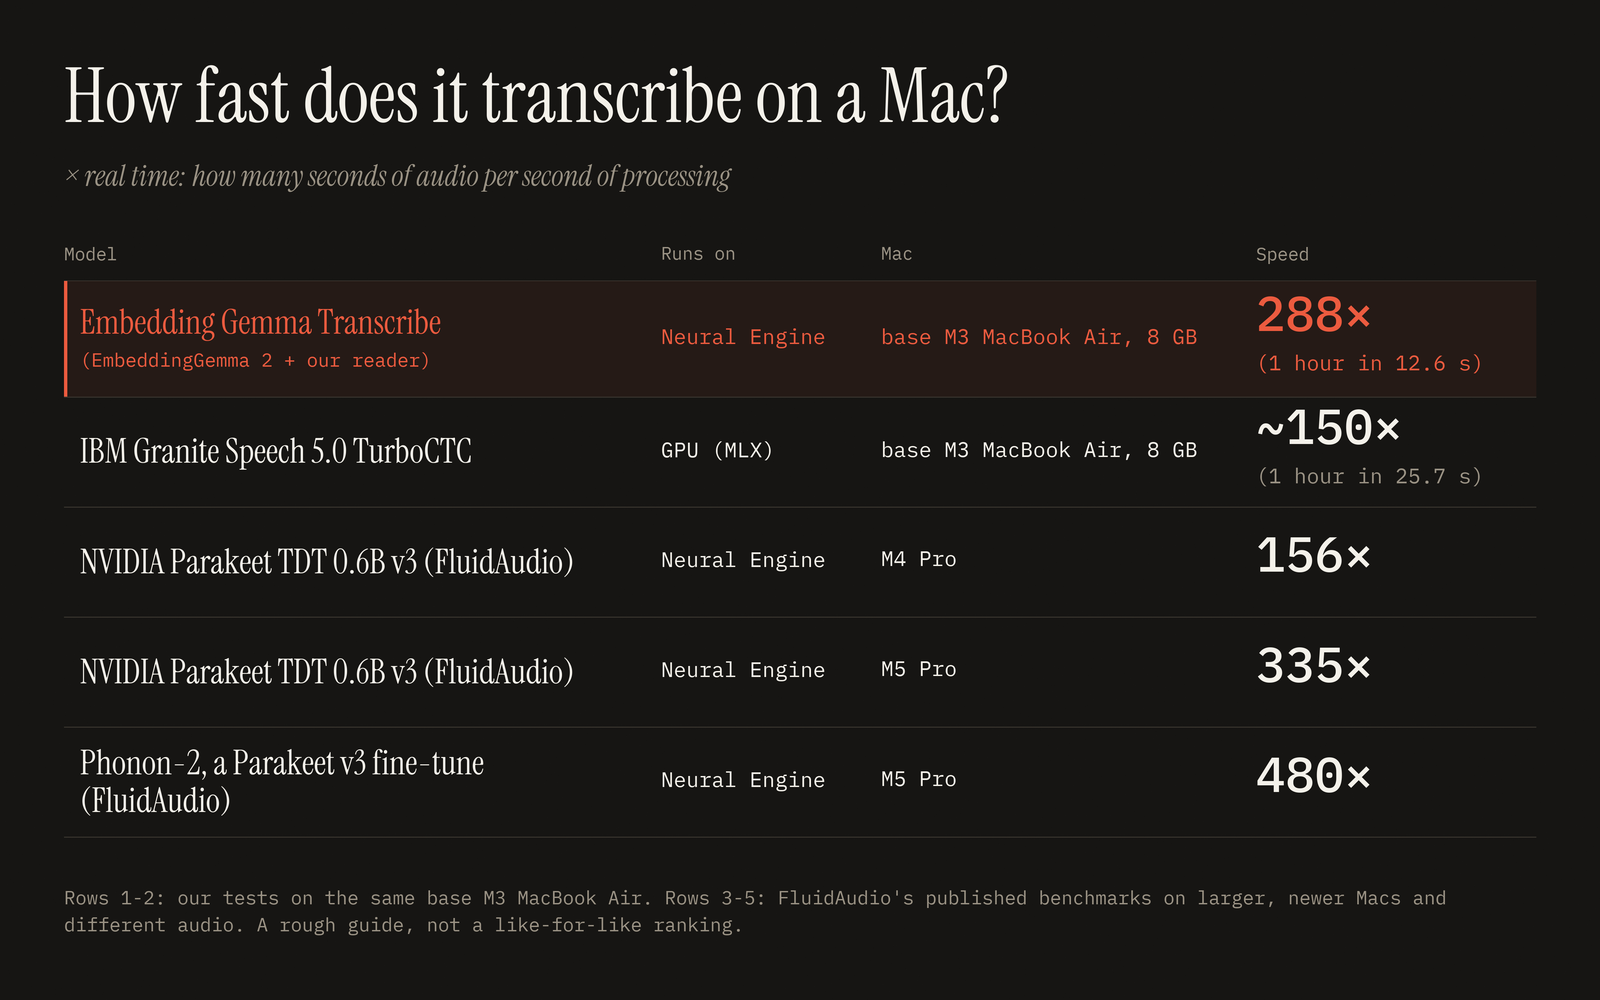
An hour of audio transcribed in about 13s on MacBook Air
An embedding model, turned into a speech-to-text model. An hour of audio in about 13 seconds on a base MacBook Air, on device.
Summary
A new speech-to-text model can transcribe an hour of audio in just 13 seconds on a standard MacBook Air. This impressive performance highlights advancements in on-device processing capabilities.
Comments (85 of ) ⌛